Haosheng (Woody) Gan
Computer Science @ GT

School of Interactive Computing
Georgia Institute of Technology
Atlanta, GA
hgan36 at gatech dot edu
Hey! I’m Woody, a first-year CS PhD student at the School of Interactive Computing, Georgia Institute of Technology🐝.
I do research on NLP and multimodal models for vision and audio. I’m interested in making AI models more interpretable and human-centered.
Currently, I am working with Professor Kartik Goyal at Kargo Lab. Before joining GT, I received my BS degrees in Computer Science and Applied Math at USC✌️. I was very fortunate to be advised by Professor Vatsal Sharan, Professor Willie Neiswanger, and Professor Mahdi Soltanolkotabi at USC, and Professor Diyi Yang at Stanford. I’m grateful to learn from my amazing PhD mentors Deqing Fu at USC and William Held at Stanford during my undergrad.
When I’m not training models or writing papers, you can find me playing or watching soccer⚽. I play left wing and people say I’m the next Vini Jr—hit me up if your team needs a good player! I also volunteer through VolunteerMatch. Feel free to reach out if you’re interested in collaborating or just chatting!
News
| Aug 24, 2026 | 🐝 Started my CS PhD at the School of Interactive Computing, Georgia Tech ! My office is at the 11th floor of CODA, feel free to stop by! |
|---|---|
| Apr 06, 2026 | 🎉 Putting HUMANS First and Text Steers Vision accepted at ACL 2026 Main! I will be presenting both papers in San Diego in early July. 📍🌴 |
| Jan 04, 2026 | AudioJudge accepted to EACL 2026 Main! Looking forward to presenting our work in Morocco in late March. 🎉 |
| Dec 02, 2025 | Will be at NeurIPS 2025 in San Diego (Dec 2-7) ! If you’re there, please catch me around the conference - always happy to chat about AI research, collaborations, or just grab coffee! ☕✨ |
Selected Publications
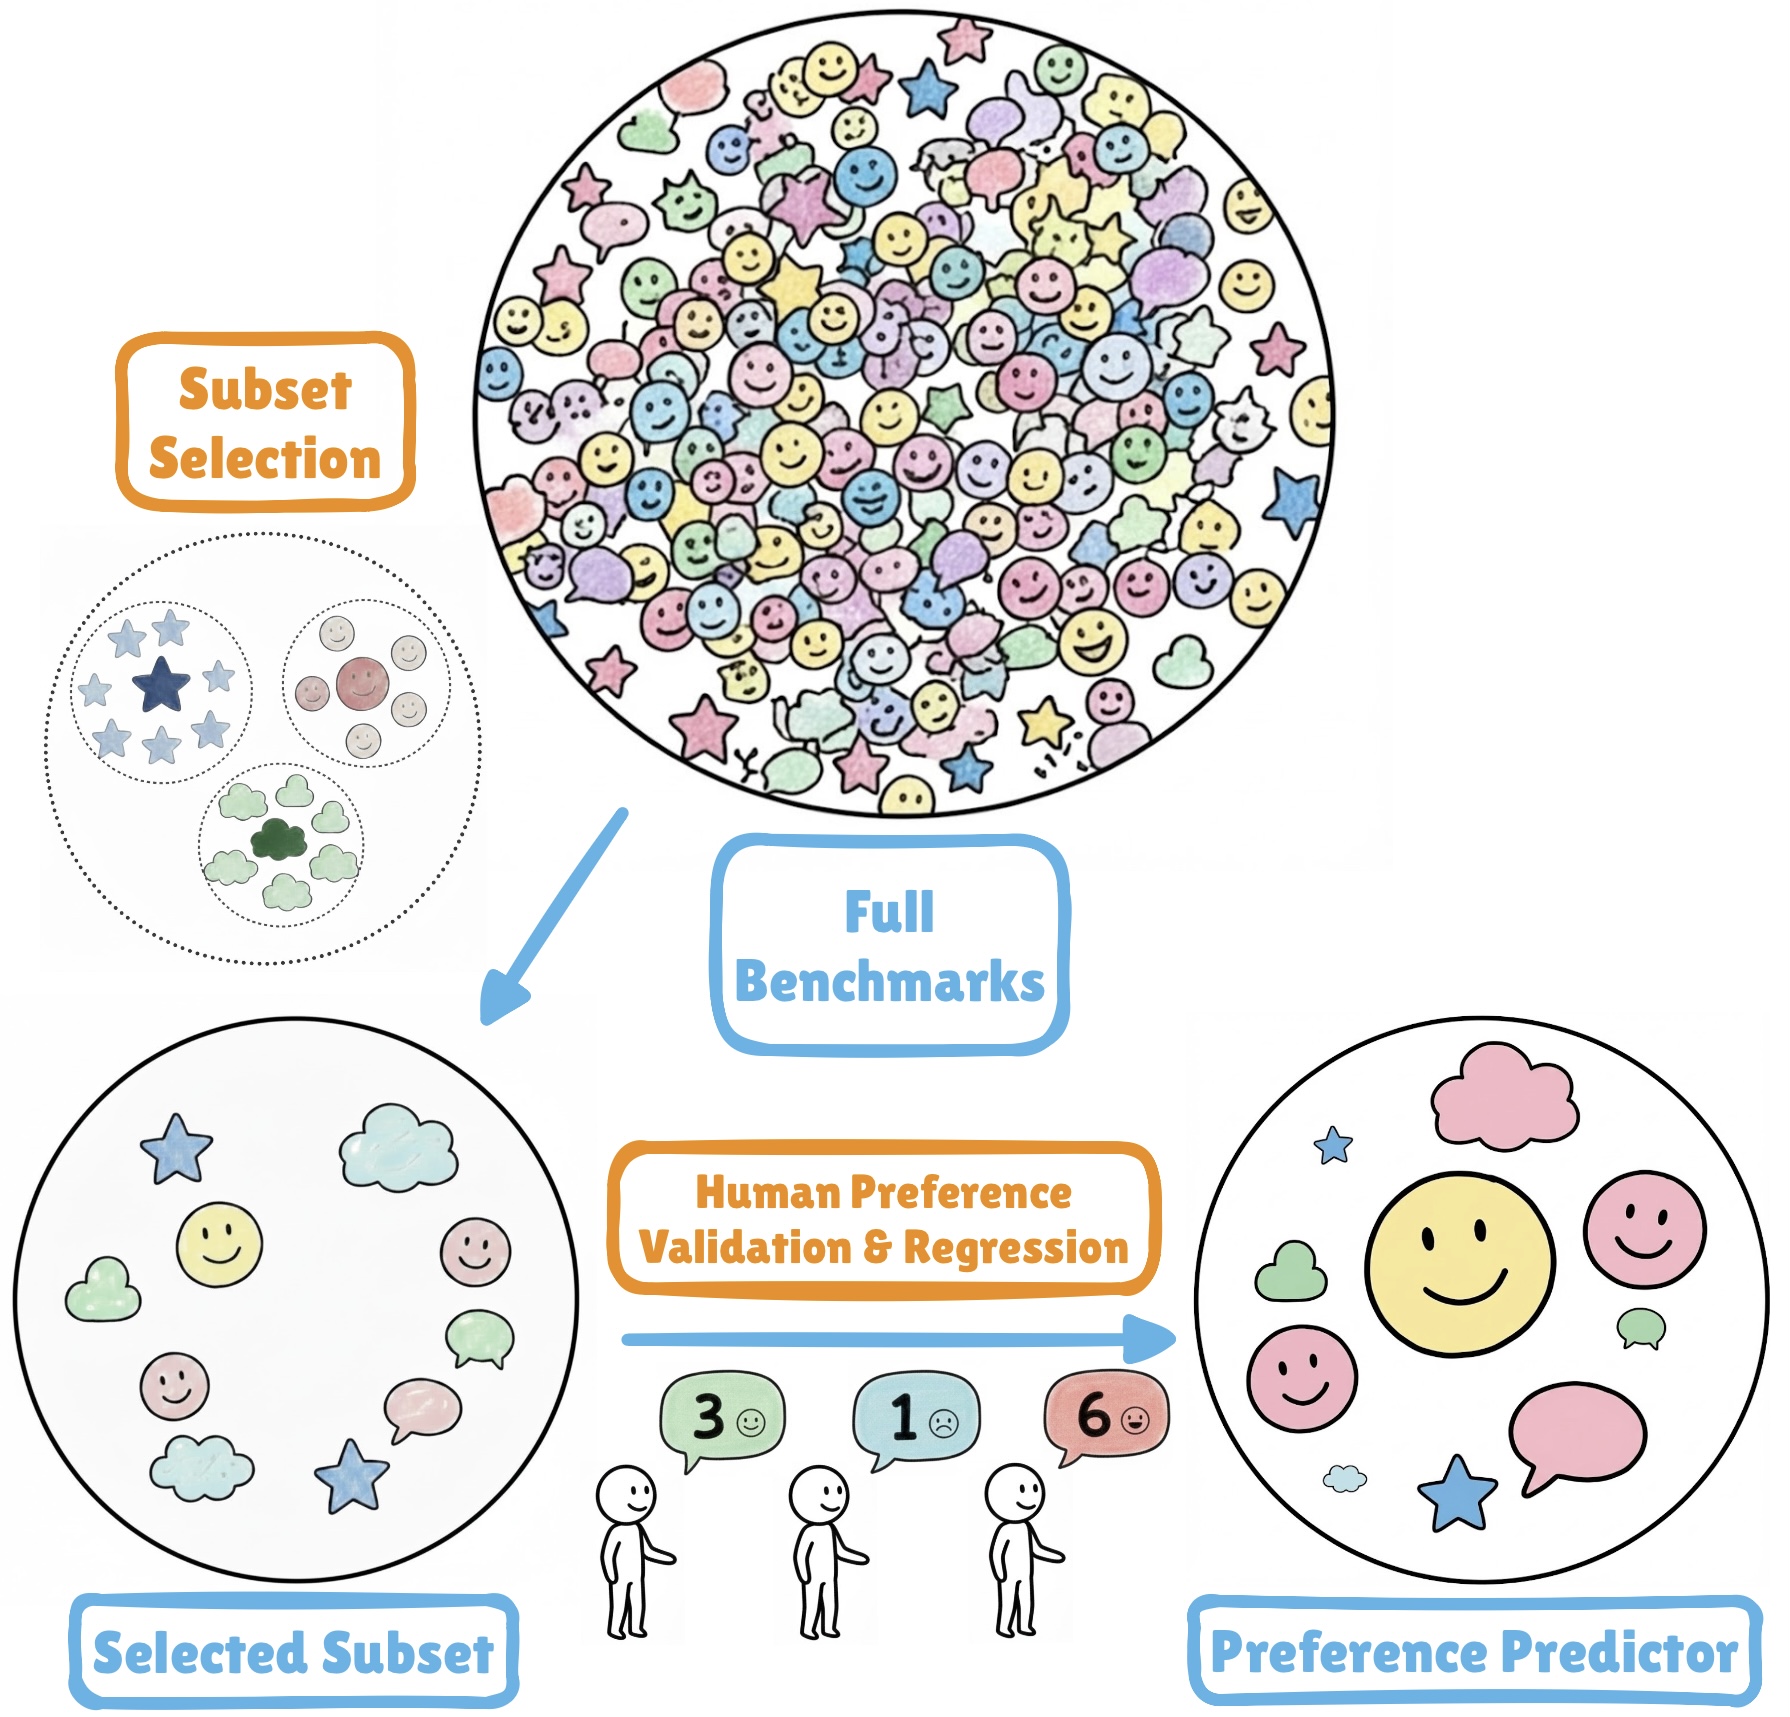
Putting HUMANS first: Efficient LAM Evaluation with Human Preference Alignment
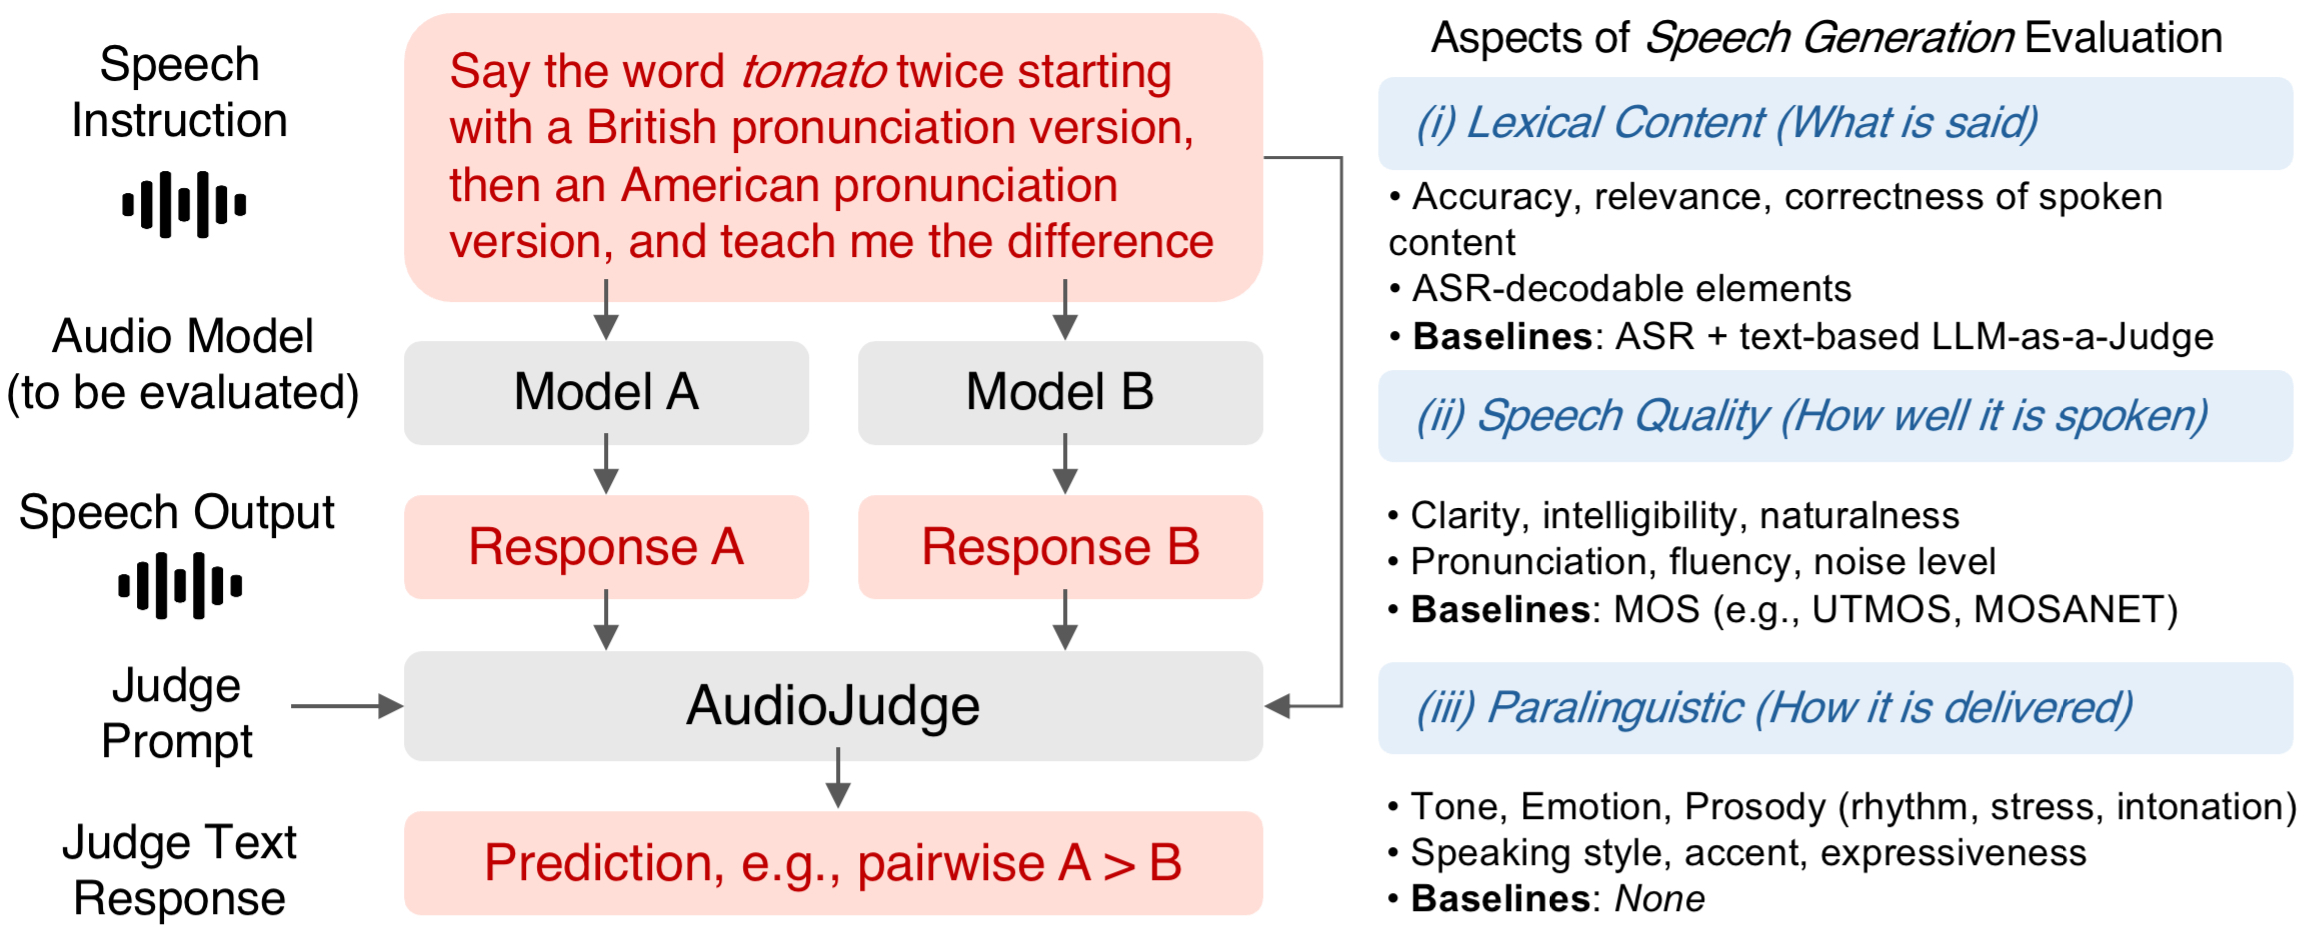
AudioJudge: Understanding what works in large audio model based speech evaluation
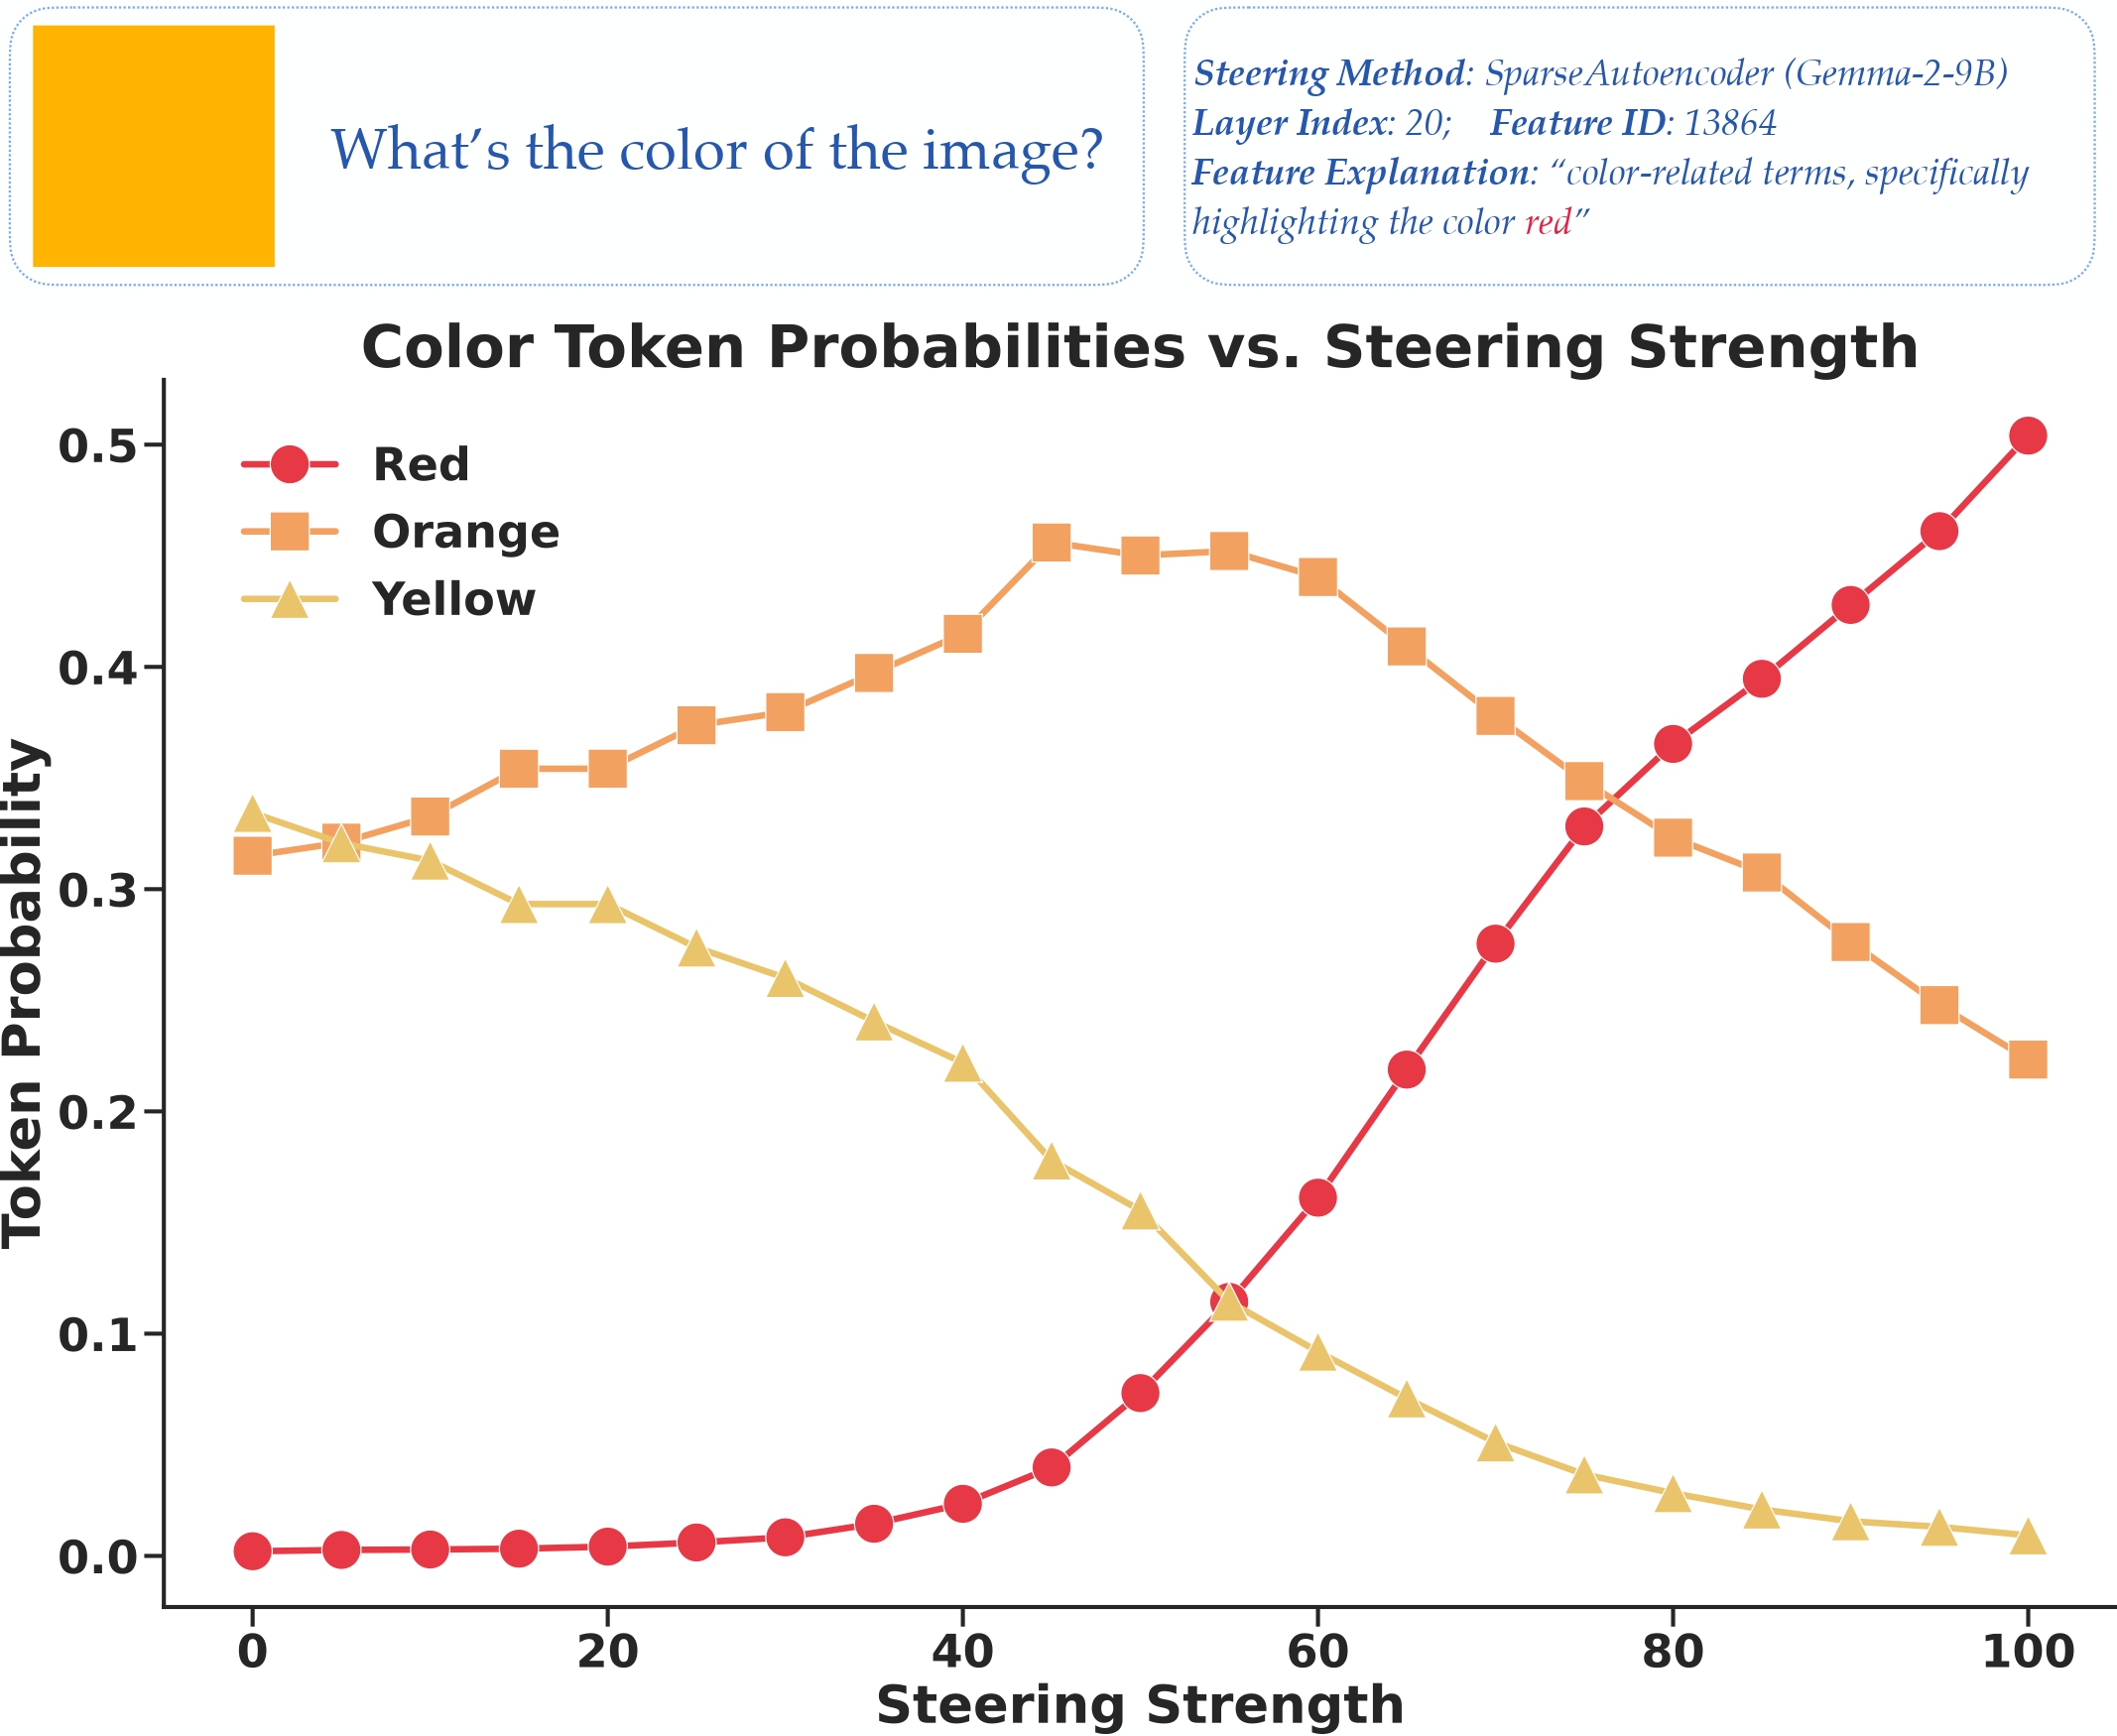
Textual steering vectors can improve visual understanding in multimodal large language models
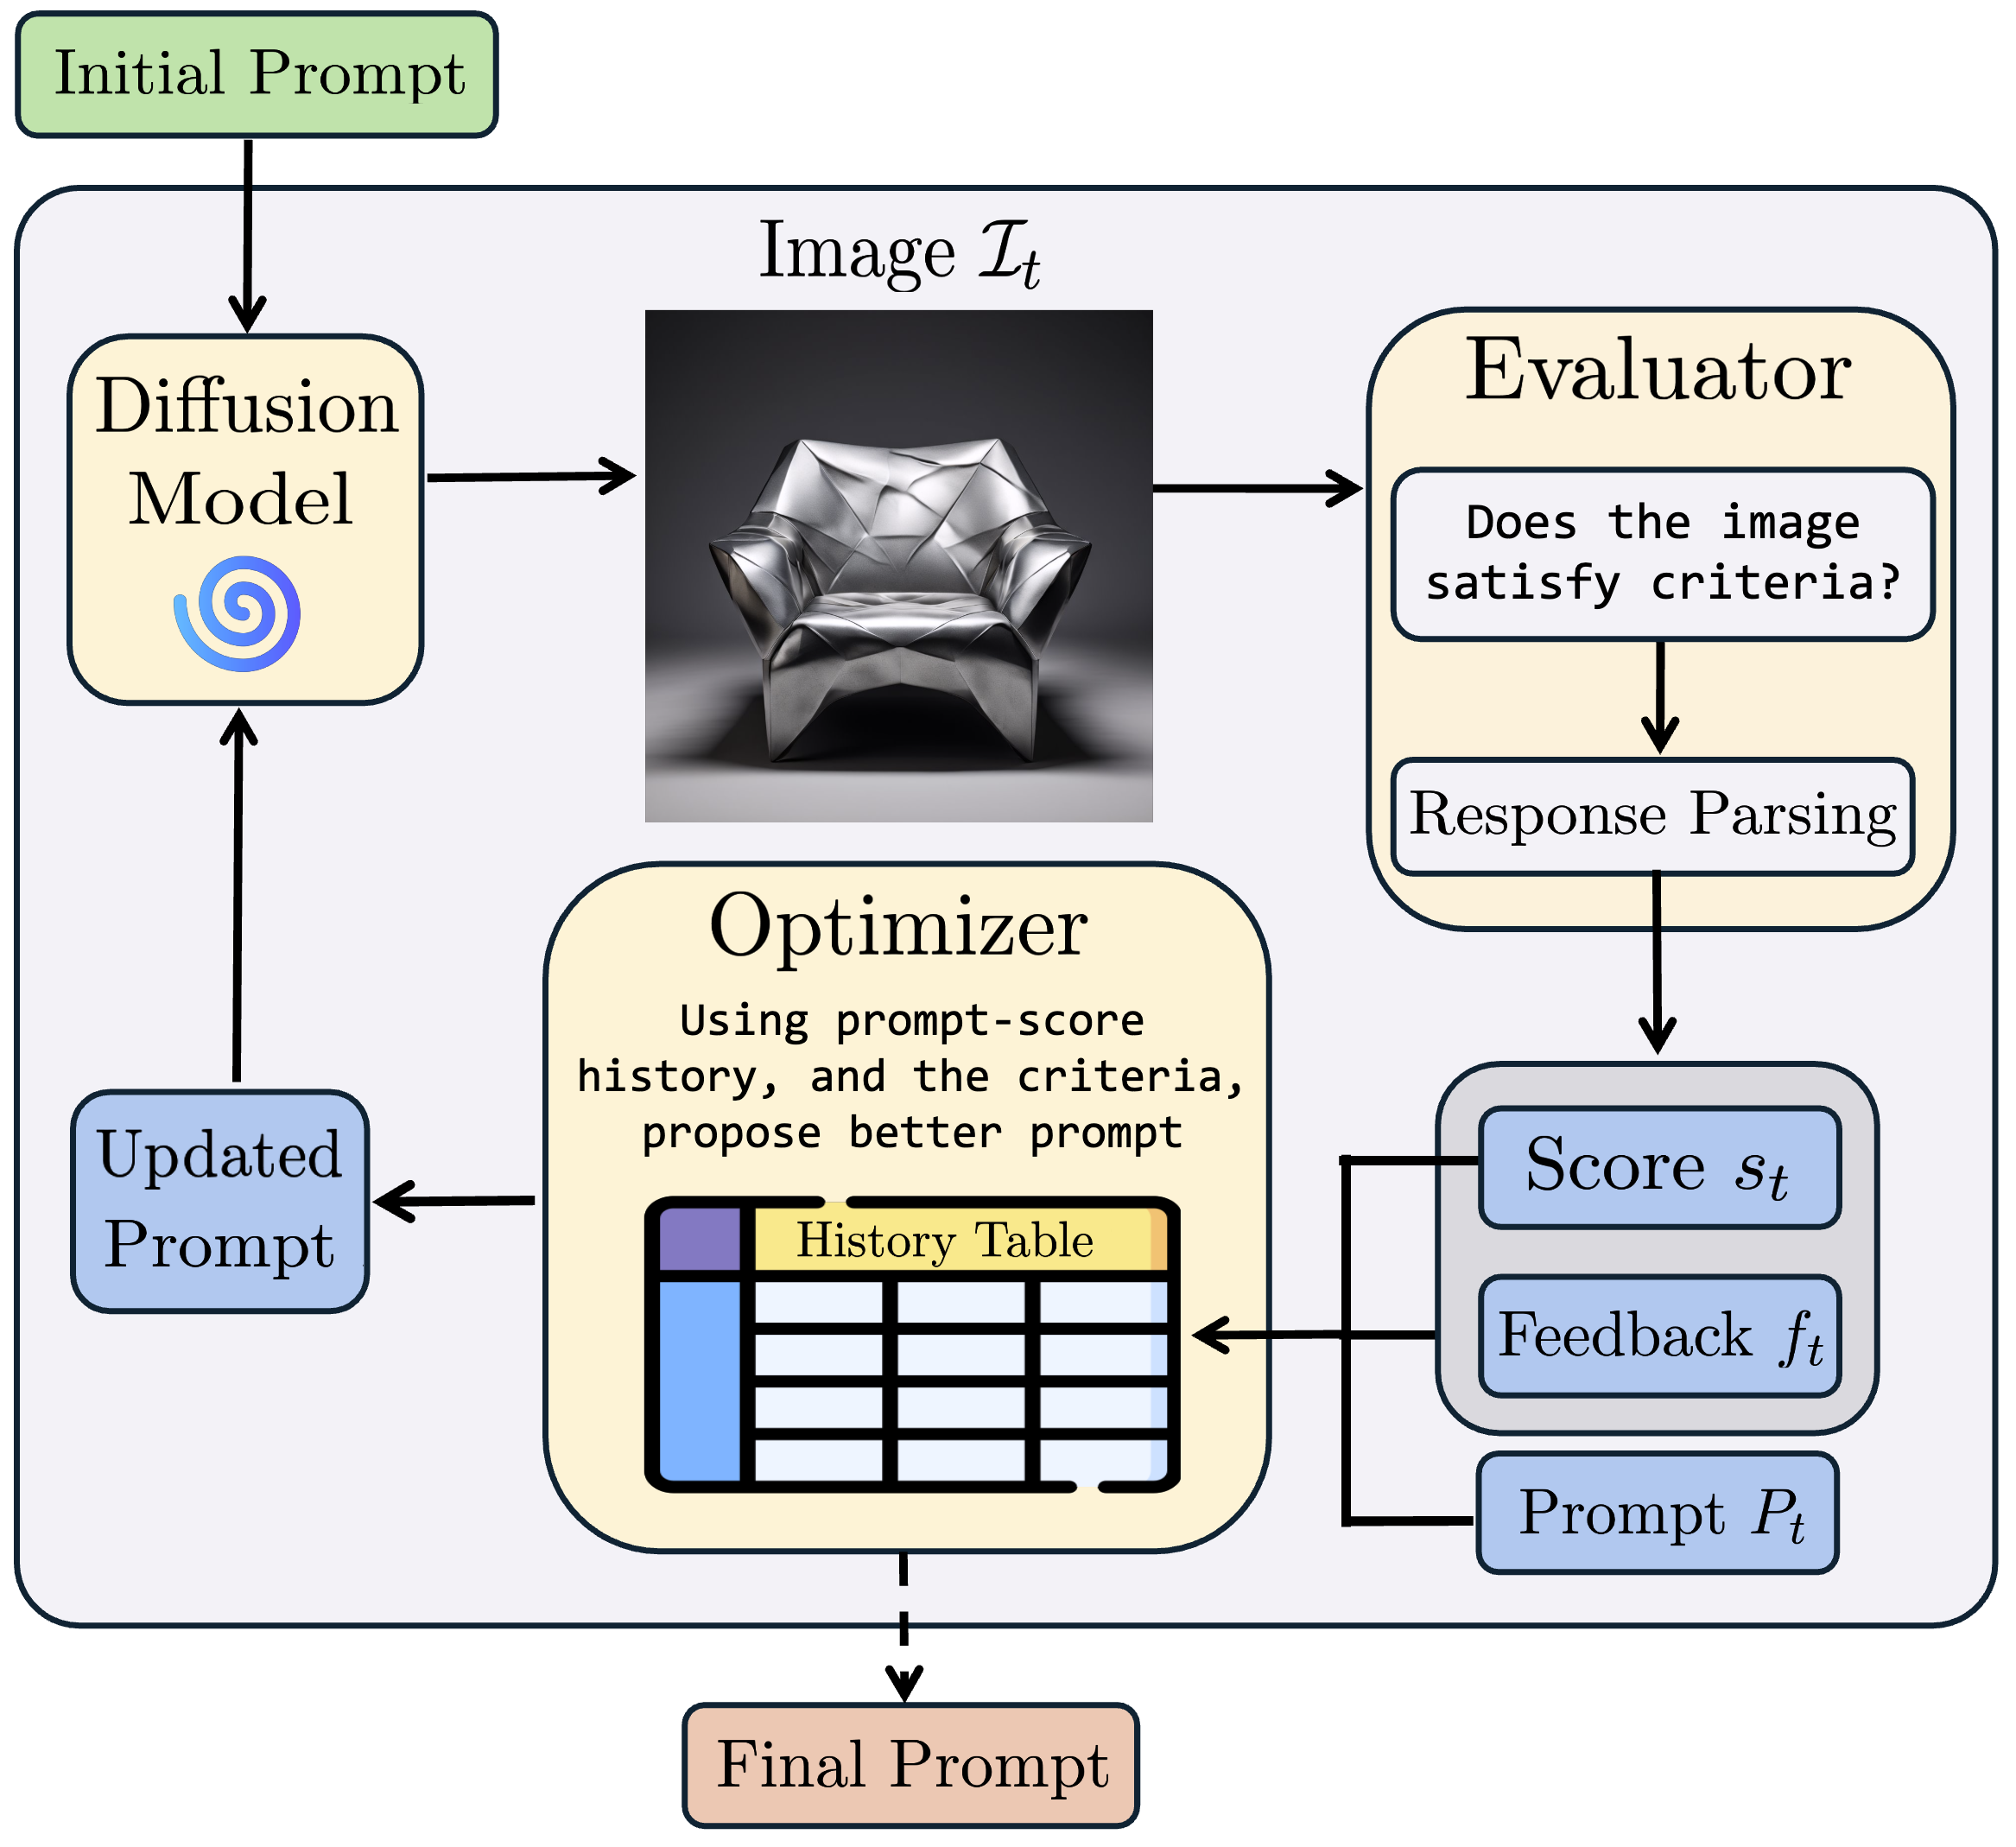
ConceptMix++: Leveling the playing field in text-to-image benchmarking via iterative prompt optimization
Projects
CAVA: Comprehensive Assessment for Voice Assistants
Benchmark Release for Large Audio Models in Voice Assistant Tasks